
Claude Opus 5
The brain. Deep judgment and complex code.
Where we use it
Contract auditing, multi-step reasoning, agents that decide.
Claude is the judgment engine in the systems we build: it thinks step by step, uses tools, reads documents and prepares the decision; whatever commits money is decided by a person. We work with Anthropic’s deployment standard, and that gives us first-hand access to its safety criteria.
We work with companies in Venezuela, the Dominican Republic, Mexico, Colombia and the US Hispanic market.
› is this deal at risk?
WHAT MAKES CLAUDE DIFFERENT
This is what Claude does inside a custom-built system, shown with demo data in each panel. Tap each one.
The effort parameter (from low to max) adjusts how much Claude reasons before answering. For qualifying a lead, low. For auditing a contract, max. The reasoning stays in view for whoever reviews it.
› problem: is this deal at risk?
‹ thinking› 28 days in negotiation vs 9 avg.
‹ thinking› competitor cited in last note
‹ thinking› profile matches lost deals
✓ verdict: high risk · escalate to manager
A lead agent coordinates sub-agents working in parallel, with curated memory between sessions and self-correction by rubric. That is how a pipeline gets followed up or an incident gets resolved end to end, with human approval on whatever commits money.
› task: reactivate inactive account
lead.plan() → 4 steps
agent.crm.read() · agent.bank.match()
agent.verify() → ok · agent.draft()
✓ account reactivated · log in CRM
The MCP connector links Claude to GitHub, Slack, Drive, Stripe, your core — any remote MCP server. Claude works as an integration layer over what you already have, with permissions per tool.
› claude.connect(mcp://your-core)
tools discovered: 14
claude.call(core.getClient, id=4821)
claude.call(core.issuePolicy, ...)
✓ executed on your real system
High-resolution vision: IDs, invoices, titles, evidence photos, screenshots. This is what validates a document against the form or extracts data from a PDF without templates.
› image: invoice.pdf (blurry photo)
extracts: RIF J-30xxxxxx-1
extracts: amount Bs. 4,820.00
cross-checks vs form → discrepancy
⚠ friendly observation generated
One million tokens of context: a client's full history, an entire contract, an operations manual. Claude reasons over the whole set, not a fragment.
› context: 312 emails + 4 contracts
claude.read(full history)
question: what did we promise in 2024?
‹ thinking› crossing 4 versions...
✓ exact clause + source email
Anthropic is an AI safety company. Claude is trained to say “I’m not sure” when the data is not in its sources and to respect the limits it is given. In B2B, that is a system requirement.
› data not present in the context
claude does NOT invent the number
‹ response› "it is not in the documents
I have · check it here"
✓ no data, no number
EXTENDED THINKING · EFFORT PARAMETER
Same problem —auditing a penalty clause— at different effort levels. More depth costs more latency: you use it where the decision warrants it.
effort
› audit the late-payment penalty clause
MODEL CONTEXT PROTOCOL
Over MCP, Claude connects to your core, CRM, Drive, Slack or Stripe without us writing a client for each one. It discovers the available tools and uses them.
› claude discovers 6 MCP servers
▶ core.getClient(4821)
crm.updateStage(deal, "Closing")
drive.read(contract.pdf)
slack.notify(#sales)
stripe.createInvoice(...)
github.openPR(fix)
THE FAMILY
We choose the model by job: speed where volume matters, depth where judgment matters.
The brain. Deep judgment and complex code.
Where we use it
Contract auditing, multi-step reasoning, agents that decide.
The workhorse. Balanced judgment/speed.
Where we use it
Lead classification, drafting, document validation at scale.
The fast one. High volume, low latency.
Where we use it
Real-time tagging, triage, massive instant responses.
CLAUDE IN ACTION
Official Anthropic Labs demo, published on their channel. It shows the model family we use inside the systems we build.
Official Anthropic video · embedded via YouTube
Official Anthropic channelBOOSTY × ANTHROPIC
In practice, the standard turns into what a committee can review: a written usage policy, autonomy levels per tool, human oversight on whatever commits money, evaluations before publishing and a reversal plan for every agent.

Anthropic deployment standard
boosty.digital × claude
“We work to the Anthropic deployment standard, and that gives us first-hand access to its safety criteria.”
WHAT WE BUILD WITH CLAUDE
Automotive · what Claude does
Scoring and classification of dealership prospects
Lead scored the moment it arrives · pipeline ordered by probability
Insurance · what Claude does
Document validation: ID, invoice, title vs form
Clear observations for the customer · the analyst reviews only the discrepancies
Fintech & B2B Payments · what Claude does
CRM with terminal opportunity scoring
Prioritized Kanban pipeline · forecast with real probabilities
Logistics · what Claude does
Fuzzy product matching + invoice PDF parsing
SKU↔order reconciliation · the PDF invoice arrives already read
Animal health · what Claude does
Voice transcription + clinical record structure
The vet talks, Claude structures · clinical record delivered as a PDF
Energy & Industrial · what Claude does
Reasoning over B2B opportunities and margins
Weighted probability explained · opportunity → project automatically
Coworking · what Claude does
Operations assistant and correspondence classification
Correspondence state machine with judgment · less front-desk load
Retail / POS · what Claude does
Voice ordering and multi-warehouse inventory assistant
Dictated order converted to order line · stock-out alerts with context
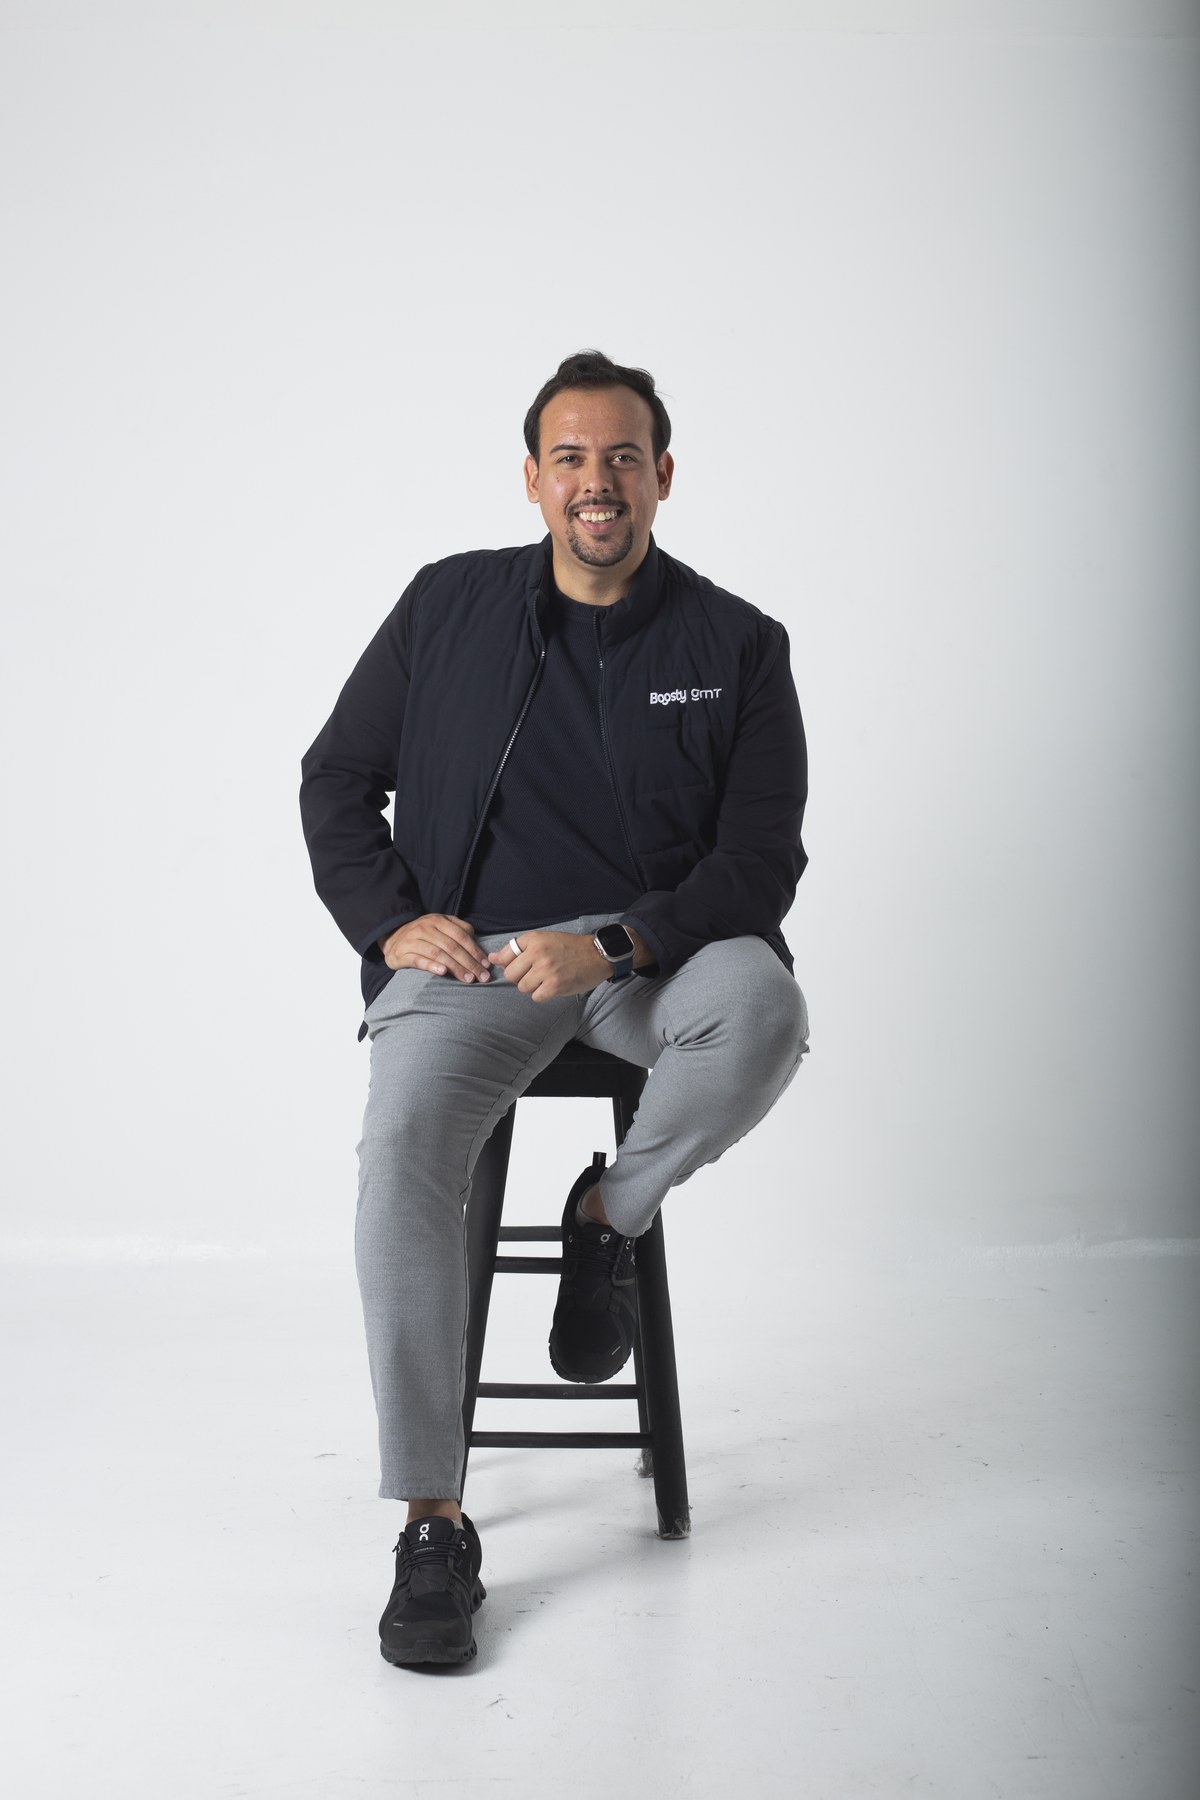
A NOTE FROM THE CEO
Picking the model is the first step. The real work is deciding what it may do on its own, how far, and what has to wait for a person. That decision belongs to the company’s leadership, and then it is written into the system.
We work with Anthropic's deployment standard because it demands of us the same thing we ask of a client: a written policy, autonomy levels per tool, evaluations before publishing, and a reversal plan. Claude reasons and leaves the reasoning in plain sight; the rest is architecture.
If you want to see what this would look like on your operation, we look at it together, you and me. You bring a real process and we tell you what we would order first, what we would build and what we would measure.
Gabriel Montiel
CEO · Boosty Digital
Because in B2B the requirement is judgment you can review. Claude reasons step by step and leaves the reasoning in view, says when a piece of data is not in its sources, and Anthropic is an AI safety company whose deployment standard we follow. That matters when the system prepares decisions about money, policies or patients.
No. Claude is a judgment layer that lives on top of the stack you already have. Via MCP or API it connects to your core, CRM or ERP. Your team keeps working where they already work — now with a copilot that reasons.
No. API/enterprise use of Anthropic does not train models with your data. We implement with the privacy and retention controls your industry requires; in regulated sectors we define the deployment mode with you.
Whichever the job calls for. Opus 5 for deep judgment (auditing, deciding agents), Sonnet 5 for the operational bulk (classification, drafting, validation) and Haiku 4.5 for real-time volume. It's almost always a mix, optimized by cost and latency.
It's Claude's ability to think step by step before responding, with an effort parameter (low→max). In practice it means you can ask for depth when the decision warrants it and speed when it doesn't — and always see the why behind its conclusion.
That every system ships with what the standard asks for: a written usage policy, autonomy levels per tool, evaluations before publishing and a reversal plan. It gives us first-hand access to safety criteria, and those criteria are applied to your operation from the assessment onward. On this site you will see it next to the official Claude Partner badge.
Scope and model are defined in the assessment. Model cost is controlled by choosing Haiku, Sonnet or Opus per task; the rest depends on what gets built first and on what volume. Book 30 minutes and we put it in writing.
The first live system on your operation — classification, reasoning and one integration — goes live when it passes its evaluation cases. The pattern already exists and is adapted to your process. Dates are set in the assessment, with your team.
GET STARTED
Book a 30-minute assessment with Gabriel. Bring a real case and we look at it with Claude reasoning live, every step in view.